The Smart Mirror turns a mirror into a style consultant. With a tap on Scan your look, a USB camera frames the garment being worn and the system recognises its colour and type, then suggests how to complete the outfit. The example runs on the Arduino VENTUNO Q board and shows how local visual AI can become part of a context-aware retail experience. Here the inference happens on the board, not on a remote server: images never leave the device, so privacy and latency stay under control.
The flow is linear and reads well from start to finish. A USB camera provides a live video stream, and the most recent frame is saved into a shared buffer. When Scan your look is tapped, the last frame is analysed locally on the VENTUNO Q board by the Qwen3-VL model, accessible through the Arduino VLM Brick. The model identifies the main garment and its colour and returns two short sentences: a description of the outfit and a style suggestion.
Two App Lab Bricks and an MJPEG stream to the browser
The result is sent to the browser and shown over the live camera view. The browser displays the live feed through an MJPEG stream exposed by the backend. The application therefore uses two App Lab Bricks: the Vision Language Model Brick and the Web Interface Brick. The first handles frame analysis, the second the page and the stream. The prompt behaviour can also be customised through a single configuration file, prompt.py.
Arduino VENTUNO Q as the compute board
USB camera for the live video stream
Arduino VLM Brick to access the model
Vision Language Model Brick for frame analysis
Web Interface Brick for the page and MJPEG stream
prompt.py to customise the prompt
Anyone who wants to rebuild the project will find the parts list here is fairly short overall. The VENTUNO Q board is the heart of the system, while the USB camera is the only sensor required. The Qwen3-VL model does not need training: it is used as it is, through the Arduino VLM Brick.
The physical assembly is not described in the example: the system relies on a USB camera connected to the VENTUNO Q board and on a backend that exposes the MJPEG stream. The rest, from the framing to the physical mirror, depends on how you want to build the mount. The software side, on the other hand, is all inside the two Bricks and the prompt.py file.
What changes with visual AI inference running locally
The interesting point is not the individual style suggestion, but where it is computed. The Qwen3-VL model runs on the VENTUNO Q board, so no image of the garment being worn is sent to a cloud service. As a result, latency stays low and privacy is simpler to guarantee: what the camera sees does not leave the mirror. The system also works without an internet connection, because inference is local.
The complete flow can be summed up like this: the camera produces the frames, the shared buffer holds the most recent one, the model analyses it on request and the browser shows the result over the live video. Every step stays on the board or on the local network, and the tap on Scan your look is the only trigger for the analysis. If you want to see how the project is built and which files it uses, the post on the Arduino blog is the place to start.
For those working in retail or in the maker world, this Smart Mirror is a concrete example of how local visual AI can power a complete, real-time user experience. No cloud is needed, no fast connection is needed, no images travelling outside the home are needed. A USB camera, a VENTUNO Q board and two well-chosen Bricks are enough.
Arduino, Qualcomm Technologies, and Edge Impulse recently teamed up with Hackster to host the Invent the Future competition. The competition attracted 4,028 registrants and 1,202 hardware applications, culminating in 153 final project submissions across a wide range of real-world applications.
There were several categories in the competition, all unified by the UNO Q board and Arduino® App Lab. The judging is officially complete and the winners have been announced, which means we get to show you the top projects that most impressed the judges and took home the awards!
These winning creations illustrate a range of uses for the UNO Q – and stay tuned, because we’ll also be shining the spotlight on many other fantastic contest submissions in the coming days.
Best Social Impact
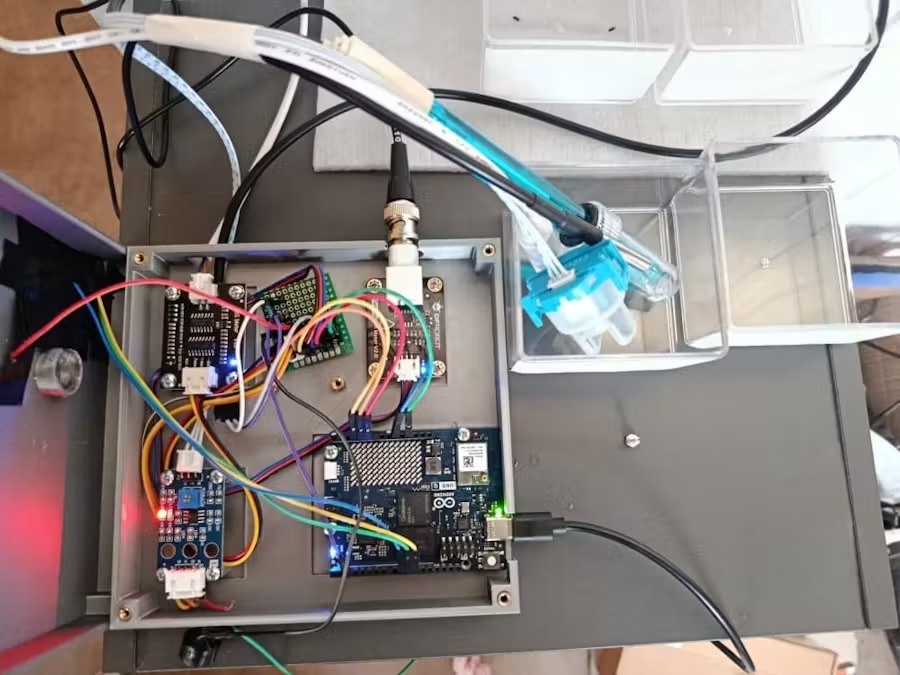
While sustainability was a consideration for every category, the Best Social Impact award went to a project built explicitly to make the world a better place. The winning project was the Smart Water Guardian AI, built by KOCHONI Biaou David Barthélémy.
This project puts the edge AI capabilities demonstrated by UNO Q to good use, by monitoring water-quality indicators in real time. Through a host of sensors, it is designed to measure everything from temperature and pH to turbidity and dissolved solids content, allowing for detection of anomalies that correlate with poor water quality – detection that could save lives.
Best in Home Automation
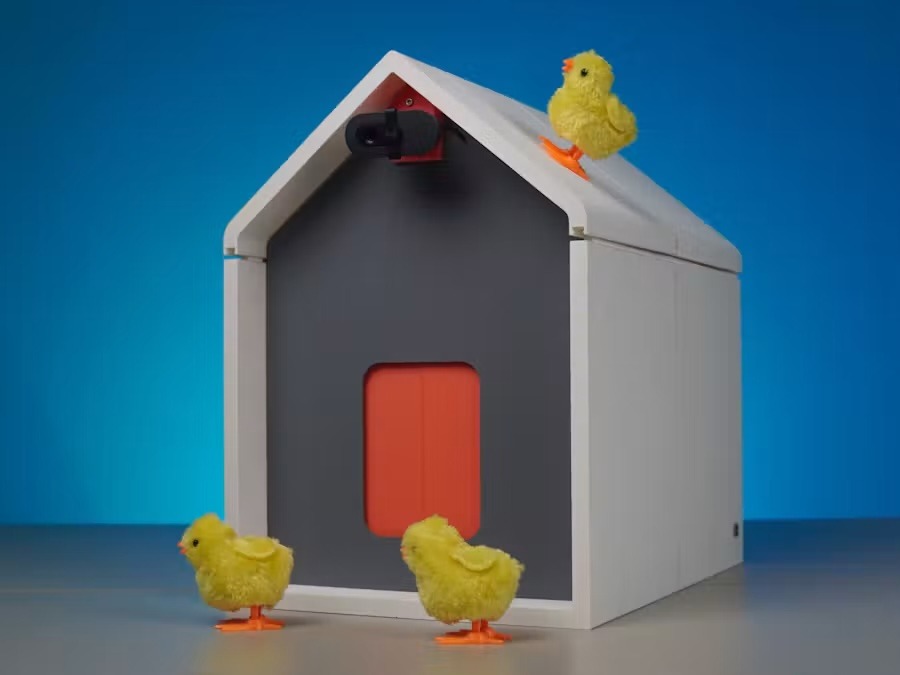
Home automation is a thriving industry, and there are all kinds of tech products you can use to build the smart house of your dreams. But what about your chickens’ house? That’s what Coders Cafe’s Smart Coop 2.0 is for.
Smart Coop 2.0 is a system design, driven by an UNO Q, for intended to support routine chicken care. It is built to handle the basics, like dispensing feed on a schedule and heating the space, using local AI models designed to detect eggs and potential predators. The creator designed Smart Coop 2.0 to make certain chicken-care tasks more convenient and to detect potential predators, including coyotes and foxes.
Best in Gaming
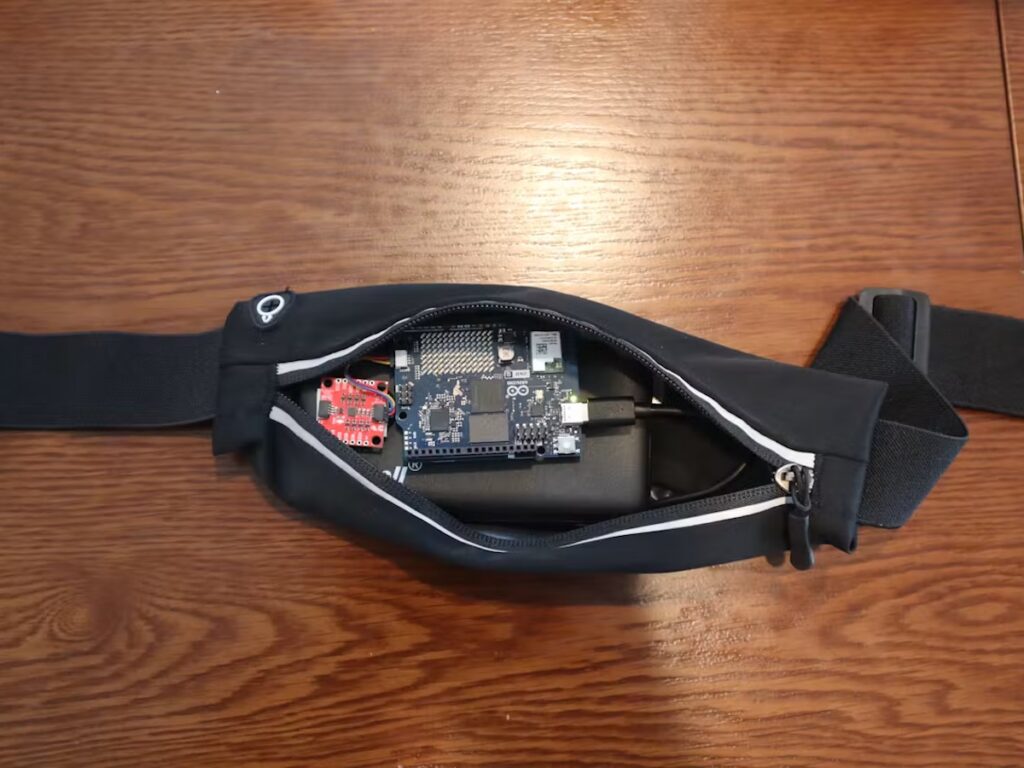
RollerCoaster Tycoon was a popular video game generally among two types of people: those who enjoy creative building and those who like maximizing metrics. Kevin Loeffler is the latter type, and he wondered how real-life roller coasters might stack up. The result is RCT IRL, which is a wearable sensor system for classifying and quantifying roller coaster rides.
“Wearable” here means an UNO Q, a SparkFun 9DoF IMU (inertial measurement unit), and a battery stuffed into a fanny pack. During a coaster ride, the dual-brain board from Arduino is structured to collect movement data through the IMU. Afterwards, three Edge Impulse models are designed to process the data and generate model-based scores labeled Excitement, Intensity, and Nausea. Together with interesting stats like ride time and maximum g-forces, those values populate a report card for the roller coaster, just like in the game.
Best in Industrial IoT
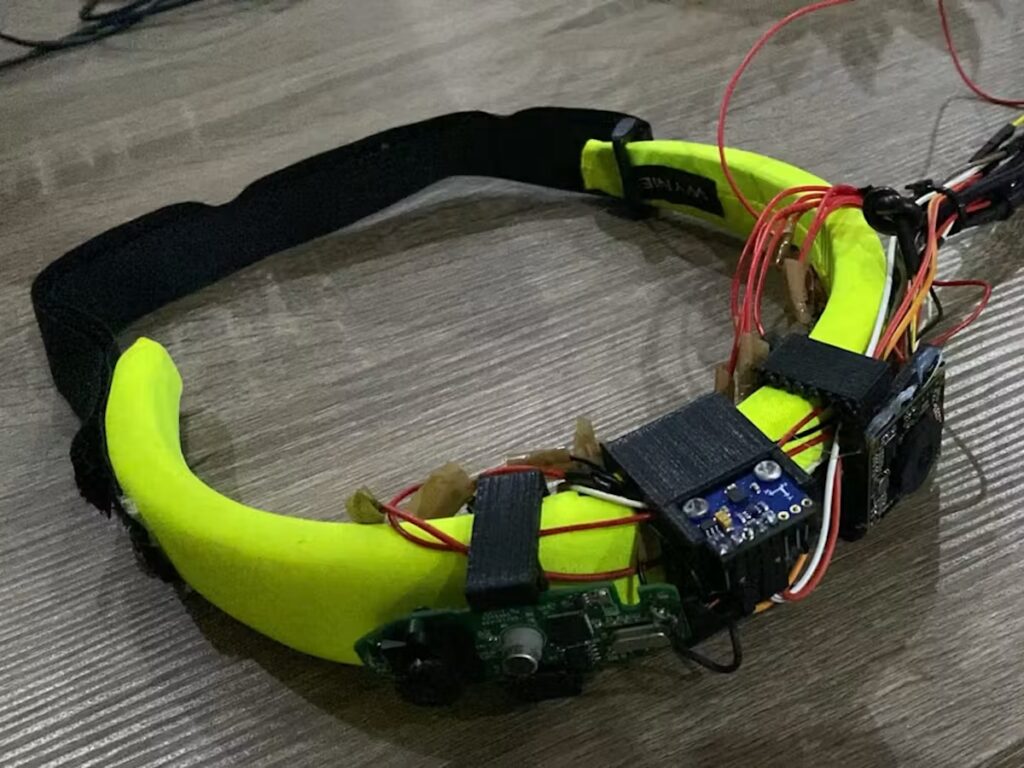
HaloSense V1 is pasquale887’s attempt to give humans new senses via neuroplasticity. In short, neuroplasticity is your brain’s ability to accommodate new functions. Of course, there isn’t anything supernatural or superhuman about that, and your brain can only work with the sensory input it receives. HaloSense V1 provides new information through the senses you already have.
Or, to put it another way, HaloSense V1 is a haptic feedback headset. Through an array of 13 haptic feedback motors, it pulses and buzzes to convey information gathered through sensors connected to an UNO Q. The project is intended to explore whether, over time, a wearer can learn to interpret the haptic patterns as information.
Best in Robotics
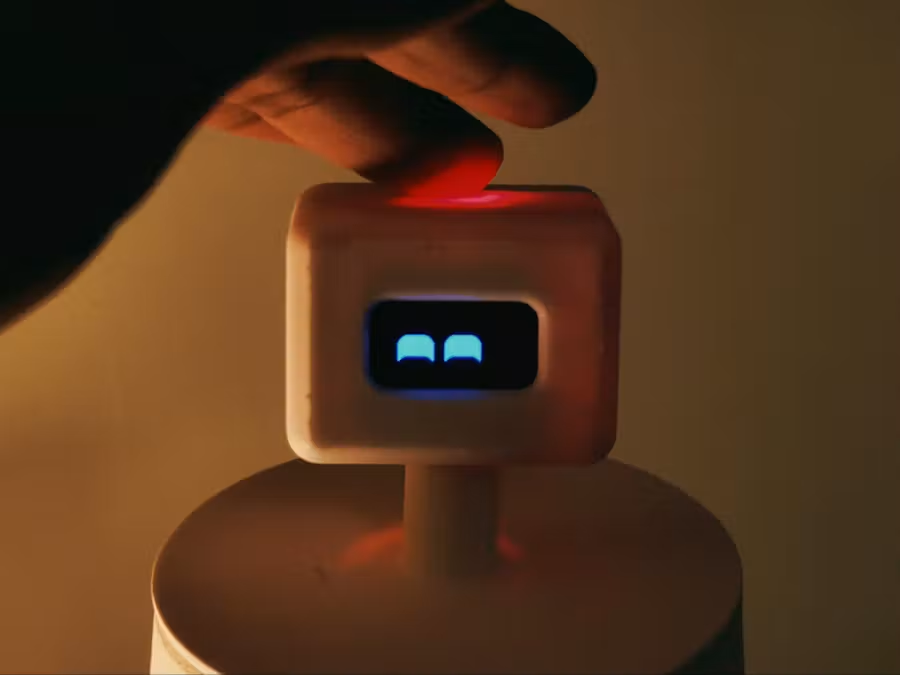
We’re in the midst of a shift in robotics towards human-friendly designs. Mohammed Akramuddin’s Curie is engineered to be as friendly as it gets. This little desktop robot is cute, with facial expressions displayed on an OLED screen. The creator designed it to help users, including those with ADHD, manage tasks.
Like all of the other projects in this competition, Curie contains an UNO Q board. It connects to various APIs, including Groq (a cloud interface that is built to let developers run open-source artificial intelligence models at high speeds), to help its owner manage their workload. It is designed to do that in the usual digital assistant ways, by taking notes and setting reminders, but also by providing more tailored assistance. It can, for example, break a complex task up into small pieces that are more approachable. It is also designed to identify potential distraction and provide a nudge to help users return to their task.
Best in Show
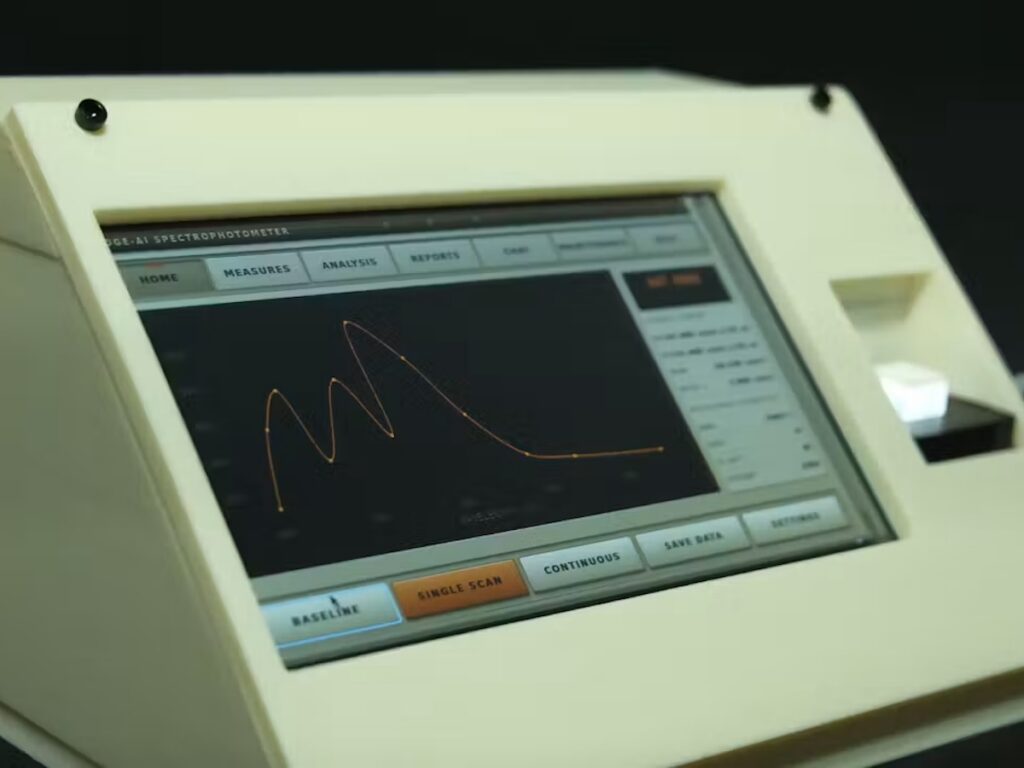
The Best in Show award went to the overall competition winner, regardless of category. The winner was Jorge Eldis González for his work on the Edge-AI Spectrophotometer, which is, as its name indicates, a spectrophotometer that integrates AI on the edge.
A spectrophotometer measures the wavelength of light, in order to detect the properties of sampled materials. That is a non-destructive analysis and can, for instance, tell you if a sample contains contaminants.
The Edge-AI Spectrophotometer is built using commercially available components, using an UNO Q and a SparkFun Electronics AS7343 Triad Spectroscopy Sensor. It then runs a machine learning inference model on the edge, which detects deviations from known baselines. The creator designed the project to make its testing workflow more accessible to less-experienced operators and to explore additional spectrophotometry applications.
Congratulations to all the winners!
Qualcomm branded products are products of Qualcomm Technologies, Inc. and/or its subsidiaries. Arduino, UNO, and the Arduino logo are trademarks or registered trademarks of Arduino S.r.l.
JBR-001 is an open source desktop robot that sees and recognizes the objects in front of it, then reacts with movements, sounds and animations. It was created by syntheticAIdata and built around the Arduino UNO Q 2GB. Inside there are three servos, a camera, a distance sensor, a buzzer and an animated display. So it is not yet another blinking ornament: it is a platform for experimenting with robotics, computer vision and edge AI on a workbench.
Assembly starts from a body of 3D-printable parts that house the board and the rest of the electronics. The head contains the camera, mounted so that it looks straight ahead of the robot. On the back of the same head sits a Modulino Distance, which continuously measures the distance to nearby objects. The arms and the rotation of the head, on the other hand, come from three servos. The mechanics are therefore easy to replicate for anyone who already has a 3D printer at home.
Overview of the hardware project
Servo pins and distance thresholds in the code
The three servos split the tasks: one rotates the head, the other two control the arms. In the code the pins are HEAD_SERVO_PIN = 9, LEFT_ARM_SERVO_PIN = 10 and RIGHT_ARM_SERVO_PIN = 11. The rest positions are all at 90 degrees, so HEAD_CENTER = 90, LEFT_ARM_CENTER = 90 and RIGHT_ARM_CENTER = 90. The servos also use a separate external power supply instead of drawing power from the UNO Q: a forced choice when three motors start at the same time.
The distance sensor decides when the robot should notice someone. In the code the detection threshold is DETECTION_DISTANCE = 200.0, while the reset one is RESET_DISTANCE = 250.0. The units are not specified in the project material, so they should be checked on the bench before trusting them. The margin between the two thresholds prevents the robot from switching on and off continuously when someone stays right on the boundary.
Heartbeat on the display, a greeting in notes and the vision model
The robot’s responses go through three different channels. The LED matrix display is driven with bitmaps of 8 rows by 13 columns, the two used for the small and large heart. In the heartbeat animation the delays are 120, 100, 160 and 700 milliseconds, and the last long gap gives the sense of the pause between one beat and the next. The sound greeting playHello instead uses the notes 523 Hz (C5), 659 Hz (E5), 784 Hz (G5) and 1047 Hz (C6), that is a C major arpeggio rising by one octave.
The most interesting part comes from the camera mounted in the head. It connects through a USB-C hub and gives the robot a front view of its surroundings. The captured images can be processed on the UNO Q with a trained computer vision model: this way JBR-001 does not just understand that something is nearby, but identifies the object and uses the result to decide how to react. Consequently the same hardware can turn its head, move its arms, change the image on the display or play a short sequence.
Arduino UNO Q 2GB as the robot’s brain
Modulino Distance for continuous distance measurement
Modulino Motors for motion control
Modulino Buzzer for sound sequences
Arduino USB-C Hub (8 in 1) to connect the camera
Three servos for head and arms
Camera mounted in the head
3D printer for the body parts
On the software side you need Arduino App Lab and the JBR-001 source code, plus a trained computer vision model for object recognition. The project has 1805 views and 2 respects. Anyone who wants to rebuild it starts here: the maker syntheticAIdata’s site, where the code and the instructions to replicate the build are. For the servos, an RC servo control module simplifies the wiring when the channels to drive grow. The project’s distance sensor is a Modulino, and as an alternative you can consider a ToF laser sensor for close-range measurement. The board everything runs on is the 2GB version, while the catalogue also lists the Arduino UNO Q 4GB in a complete kit: same family, more memory for vision models.
Expense calculations in the industrial world tend to be unintuitive to individuals, because service and maintenance often consume larger chunks of the budget than the equipment itself. For that reason, modifications to equipment are usually seen as too risky to justify — they can too easily impact serviceability. So, what do you do when you want to bring an old piece of equipment into the modern age? Michael Bryan Ross’ solution was to use AI to look at analog gauges.
Ross wanted to address a simple and common problem: the equipment has an analog gauge and it would be nice to have that value available in digital form for monitoring and logging.
Most of us, when presented with that problem, would take the easy and seemingly reasonable approach. That might be something like replacing the analog gauge with a microcontroller outfitted with an ADC (analog-to-digital converter).
But very few plant managers or manufacturing engineers are going to give the green light on a modification like that. Not only is there upfront downtime to consider, but it also puts the equipment and future serviceability at risk.
Ross’ solution, on the other hand, is much easier to approve. That’s because it doesn’t require any modification to the equipment at all. In fact, it doesn’t even need to make physical contact with the equipment.
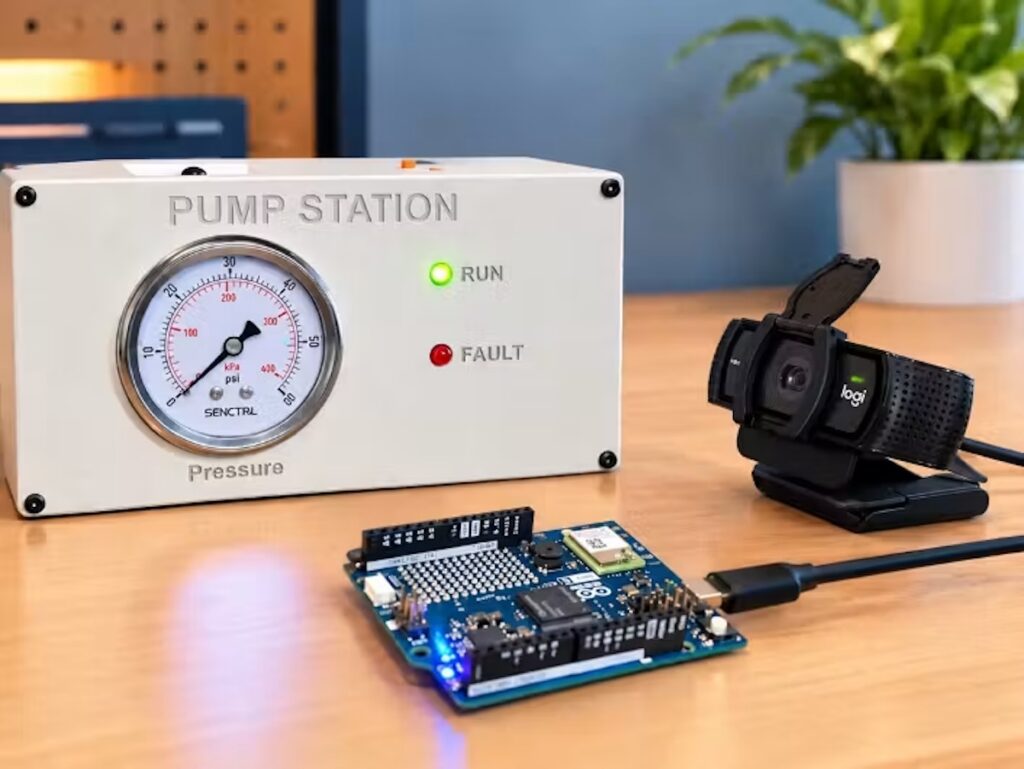
It works by using a camera and AI running on the edge to read the analog gauge. In this case, “the edge” is an inexpensive Arduino® UNO Q and it looks at the gauge through a standard USB webcam. The UNO Q runs a MobileNetV3-Small model through ONNX Runtime.
To test that — and to gather the images needed to train the model in the first place — Ross built a physical device with a real analog gauge driven by an actual pressure sensor. To create a training data set, Ross simply collected a bunch of images of the gauge’s needle in different position, then had GPT-5.6 read the black ticks to classify them by numeric value.
Ross acknowledges that the resulting model isn’t perfect. In particular, it tends to lose accuracy at very high and very low ends of the gauge range. But that is a fixable problem (largely through training). The concept holds: that this approach makes it possible digitize analog gauges, without spending much money and without modifying equipment.
Every day, hundreds of thousands of kits are prepared in warehouses before components ever reach an automotive production line. While robots have become commonplace in modern manufacturing, many upstream logistics activities still rely heavily on human operators performing repetitive pick-and-place and kitting tasks.
What if robots could learn these operations the same way humans do: by simply watching a demonstration?
That question was at the heart of I-GENIUS, a research project coordinated by MYWAI within the European ARISE initiative with Centro Ricerche FIAT (CRF) and the University of Genoa’s Department of Mechanical, Energy, Management and Transportation Engineering (DIME).
The project explored new approaches to Human-Robot Interaction, combining AI, computer vision, and robotics to enable machines to acquire manipulation skills from minimal human guidance.
One of the project’s key outcomes was VILMA (Visual Imitation Learning for Manipulation Activities), an AI-powered toolkit integrated into MYWAI’s EDGE AI middleware platform. VILMA helps enable robots and humanoids to learn complex manipulation tasks from one-shot human demonstrations, aiming to significantly reduce programming effort while improving flexibility in dynamic industrial environments.
The technology was evaluated in a large-scale automotive warehouse use case developed together with CRF and reproduced within the robotics laboratories at DIME.
Today, MYWAI is bringing this technology to a broader community of developers, makers, and robotics innovators by porting the VILMA Toolkit to new Arduino products powered by Qualcomm Dragonwing processors, including both the Arduino®UNO Q and VENTUNO Q boards.
This demonstration showcases the potential for edge-native robotics applications that use imitation learning techniques on hardware platforms built to support compact form factors and efficient power consumption.
At the iGenius final presentation, the founder and CEO of MYWAI, Fabrizio Cardinali, stated: “The dual-brain architecture of the UNO Q and VENTUNO Q platforms is an ideal foundation for MYWAI’s next generation of Edge AI robotics. After validating distributed intelligence concepts within the ARISE I-GENIUS project, we are now leveraging these platforms to bring World Action Models closer to the edge through the latest release of the MYWAI EdgeAI Management Platform and its mobile tracker, HEDGELOG. By combining One-Shot Video Imitation Learning with edge-native AI execution, we aim to enable robots and intelligent industrial machines to acquire, distribute, adapt, and execute complex manipulation skills with unprecedented flexibility and scalability.”
Watch the full demonstration of the I-GENIUS project and see VILMA in action in this video.
The MYWAI VILMA agent
VILMA is a visual imitation learning toolkit that helps enable robots to learn manipulation tasks from human demonstrations. It is designed to process RGB-D recordings or MP4 videos to extract hand and object trajectories, generate reusable robot skills using Dynamic Movement Primitives (DMPs), and produce robot-ready trajectories for playback. It is constructed to serve as the demonstration learning module, supporting rapid robot programming, skill reuse, and deployment.
The AI pipeline
One-shot demonstration acquisition
The one-shot demonstration acquisition step is set to record a human performing the task or retrieve an existing demonstration from a selected MYWAI equipment event. It stages the video, RGB frames, depth data, and camera parameters, and allows the user to select the target object for tracking. This information provides the inputs required by the remaining pipeline stages.
Hand detection
Using MediaPipe, this stage is structured to detect 21 hand landmarks in each RGB frame and combine their 2D positions with depth data to calculate 3D camera coordinates. For demonstrations loaded from MYWAI, the staged RGB and depth data are processed through the same pipeline. Kalman smoothing and previous-position retention improve tracking robustness, and the resulting trajectories can be saved back to the MYWAI event.
Object detection
Using a YOLO model, this stage is designed to detect or track the object selected through the local or MYWAI interface. It combines the bounding-box centre with depth information to calculate the object’s 3D position, applies Kalman smoothing, and saves the trajectory and annotated frames. These results can then be included in the pipeline artifacts stored in MYWAI.
Trajectory and segmentation
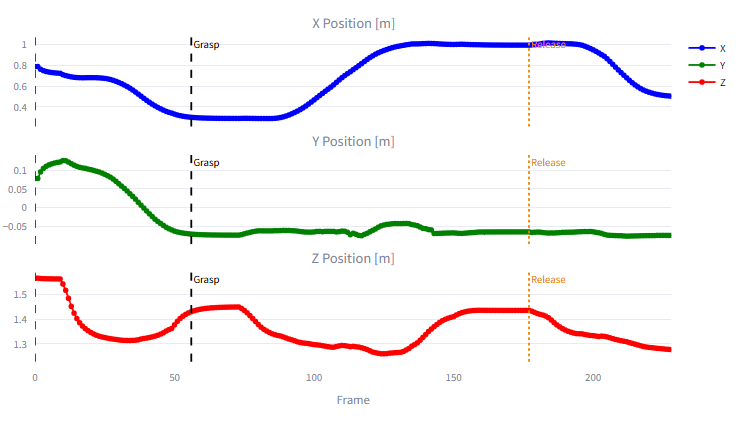
This stage is constructed to load the smoothed hand and object trajectories, estimate the grasp point from the hand’s proximity to the object, and detect the release point from the object’s movement and stabilization. It uses the hand trajectory as the main motion path and divides it into reach, grasp, move, release, and post-release phases. The trajectories, event indices, and segmentation metadata can be packaged as MYWAI event data, a time and space data fusion format developed by MYWAI for its AI-IoT management platform particularly geared towards Multimodal AI and, next, towards World Action Models.
DMP generation
The DMP-generation stage is designed to learn separate Dynamic Movement Primitive models for the reach and move phases. It evaluates different regularization values, selects the model that provides the best accuracy and smoothness, validates the reproduced motion, and saves the trained models and trajectories. These DMP artifacts can be uploaded to MYWAI with the other pipeline results for later retrieval and reuse.
Demonstration
The demonstration stage is structured to convert the generated DMP trajectory into Cartesian robot positions using the configured scale, offset, and rotation, then apply inverse kinematics to calculate the joint trajectory. The robot model may be loaded from the selected MYWAI equipment, and the resulting motion is displayed through the MYWAI 3D Viewer, synchronized with the recorded video and its grasp and release events.
DMP adaptation with new goal and new object
The adaptation stage is set to load the learned skill – either from the current pipeline or a restored MYWAI event – and detect a new target object using RGB and depth data. It calculates the 3D offset between the original and new objects, redirects the reach and move trajectories toward the new pick and release positions, and preserves the demonstrated motion characteristics. The adapted trajectory can then be visualized with the MYWAI 3D Viewer or sent to the robot.
Live streaming adaptation and UNO Q and VENTUNO Q support
The Live stream phase represents the deployment and real-time inference stage of the VILMA Agent. While the initial learning phase is conducted on the MYWAI platform to generate Dynamic Movement Primitives (DMP), the Live stream phase focuses on shipping these DMPs along with a fine-tuned YOLOv8 model, supported today on UNO Q and VENTUNO Q.
Architecture and components
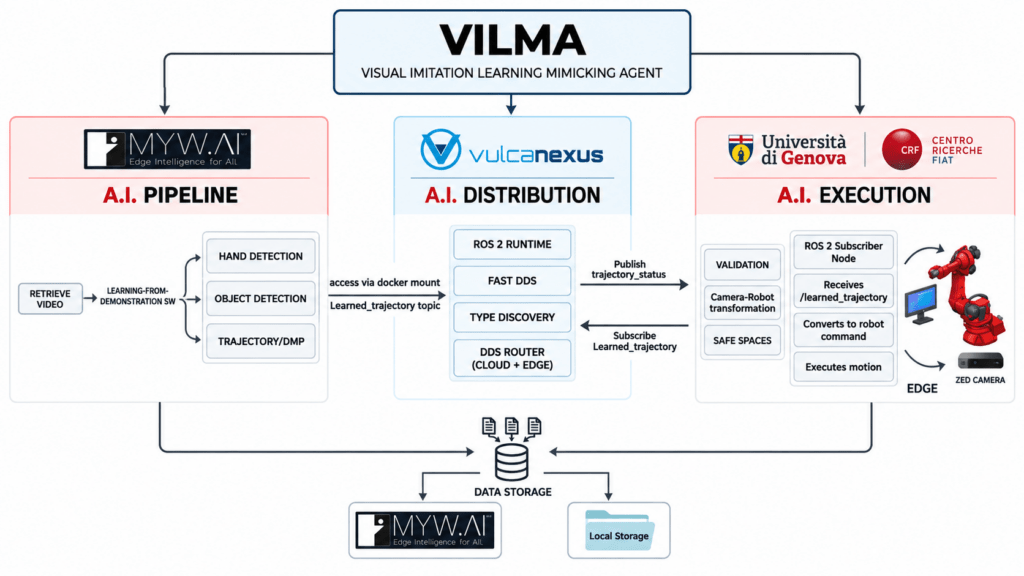
As illustrated in the system schematic below, the architecture is designed as a distributed setup divided into an Edge AI Layer for intelligence and a Communication Layer for hardware interfacing.
Let’s break down how the live stream pipeline is working considering the VENTUNO Q version.
1. Edge AI layer (VENTUNO Q)
Running on VENTUNO Q, this layer is structured to handle high-level decision-making.
VILMA Control Loop: The primary application logic responsible for the overall control loop. It It is designed to orchestrate object detection and performs DMP Adaptation to translate learned human motions into the current physical environment.
Video Object Detection Brick: This component runs on VENTUNO Q to manage the inference flow. It receives the incoming video feed and communicates with the inference service.
Docker: YOLOv8 Inference Service is formed as a containerized service that runs the quantized YOLOv8 model. This model is designed to be fine-tuned and deployed via the Edge Impulse platform using the “Bring Your Own Model” feature.
2. ROS 2 communication layer (Workstation)
A separate workstation connected directly to the devices manages the high-bandwidth data streams and robotic control via ROS 2.
ROS 2 Streaming Node: Interfaces with the ZED Camera/Depth Sensor to capture raw visual data, publishing it as a /camera_feed to VENTUNO Q.
ROS 2 Command Node: This node acts as a wrapper around the Fairino Python SDK. It is engineered to serve as the receiver for the /learned_trajectory sent from the edge device, utilizing the SDK to directly control the robot and help ensure it accurately follows the planned trajectory.
3. Physical hardware
External hardware is connected to complete the runtime VILMA ecosystem, namely:
ZED Camera: The stereo camera which is engineered to capture the image and depth data required for the vision system.
Fairino FR10 Robot: The robotic arm that is constructed to execute the pick-and-place tasks based on the trajectories computed by VILMA.
Component communication and data flow
The communication between these components is designed for low-latency execution as shown in the schema above:
Vision Input: The Workstation is engineered to stream the /camera_feed (image and depth) to VENTUNO Q.
Edge Inference: The VILMA Control Loop is designed to utilize a WebSocket stream to send frames to the Docker YOLOv8 Inference Service. The service returns the detected object bounding box to the control loop.
Motion Adaptation: The system is structured to take the detected object positions and adapts the human-learned DMP to calculate a precise pick-and-place trajectory.
Robotic Execution: The resulting /learned_trajectory is published back to the Workstation’s ROS 2 Command Node, which drives the Fairino FR10 robot to complete the task.
This modular approach is designed to allow the heavy vision processing and motion adaptation to happen on the edge (VENTUNO Q) while leveraging the robust ROS 2 ecosystem for robot communication and sensor streaming.
To learn more about the project and MYWAI’s EDGEAI Platform and Middleware, visit myw.ai.
Qualcomm branded products are products of Qualcomm Technologies, Inc. and/or its subsidiaries.
Arduino, UNO, and VENTUNO are trademarks or registered trademarks of Arduino S.r.l.
A lot of newer 3D printers incorporate sophisticated sensor suites and cameras to detect problems with print jobs, like the dreaded “spaghetti failure.” Those work pretty well and prevent wasted time, wasted filament, and even damage to the printer. But what if you don’t have a printer with those features? Or if you want to protect your privacy? Then you can follow Philipp Schweizer’s guide to use an Arduino UNO Q as your local 3D printing watchdog.
Schweizer’s approach is to use the UNO Q and a camera to detect anomalies, rather than specific problems. It doesn’t look for spaghetti failure or clogging. Instead, it looks for a normal print. Anything abnormal gets flagged. That dramatically reduces the amount of training data required and accounts for all visible issues, whether they were anticipated and trained for or not.
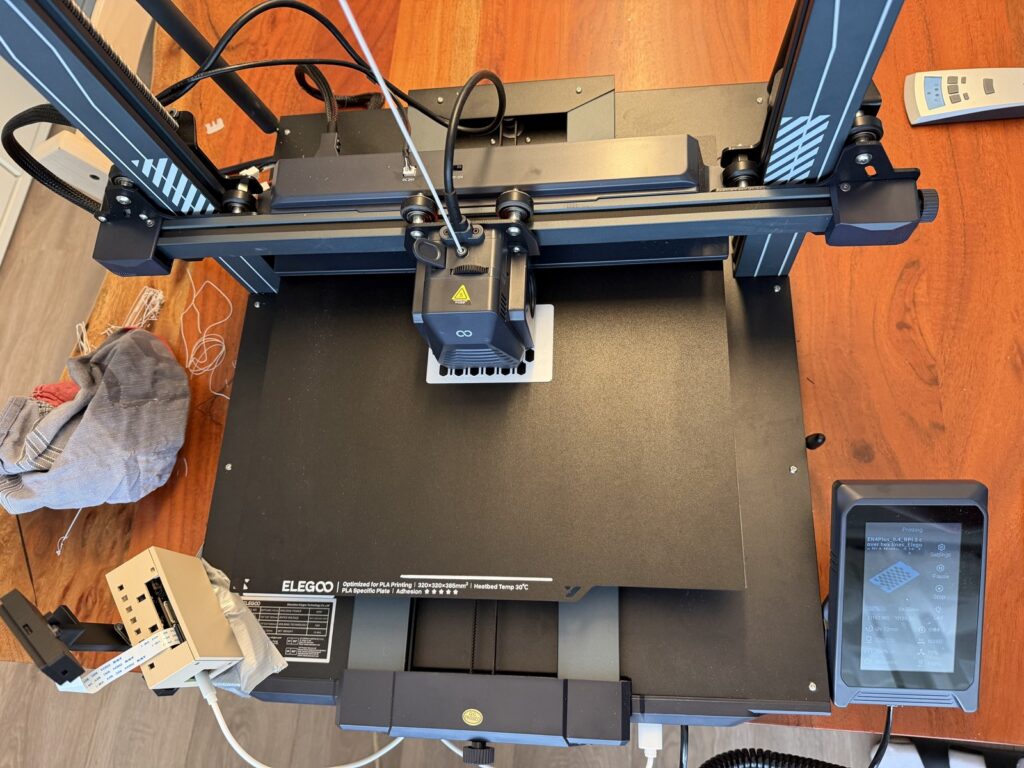
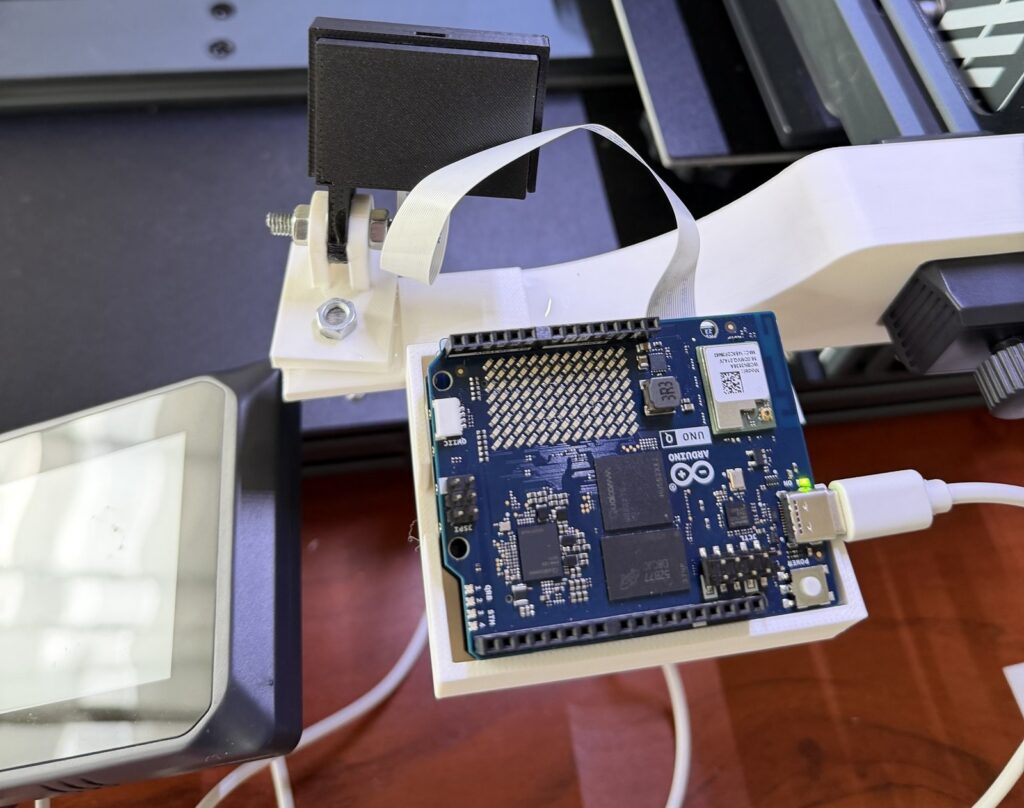
The hardware required for this includes an UNO Q (4GB model), an Arduino®UNO Media Carrier, an V2-style IMX219 camera module, and a custom-printed mount with fasteners. The goal with that mount is to point the camera at the hot end and below, so it will likely require customization to fit the 3D printer model in question.
All of the magic happens thanks to the FOMO-AD anomaly model from Edge Impulse, implemented through Arduino App Lab. That requires training on images of normal prints and Schweizer explains how it is easy to collect those automatically during print jobs. By keeping the image resolution low (632×480), the overhead remains minimal and the model efficient.
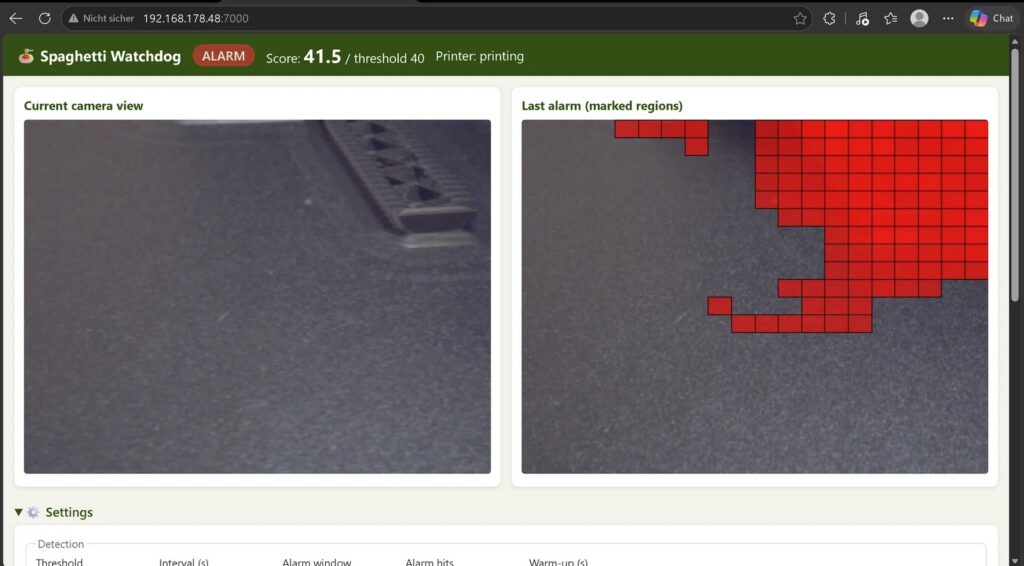
As Schweizer points out, an overeager watchdog is worse than not having a watchdog at all. For that reason, Schweizer built his app so that it only automatically pauses a print if at least three out of the last four images show an anomaly. When that is the case, it pauses the job through the Moonraker API (standard for Klipper-based systems). For those who don’t use Klipper, it is possible to integrate the watchdog into Octoprint or other control software. It also sends an MQTT message compatible with Home Assistant for notifications and hosts a webpage where the status is visible.
All of that works without leaving the local network, so it is great for those who value privacy and security. Even if those factors don’t concern you, this is an affordable watchdog solution that doesn’t require a specific 3D printer model or a subscription service.